Abstract
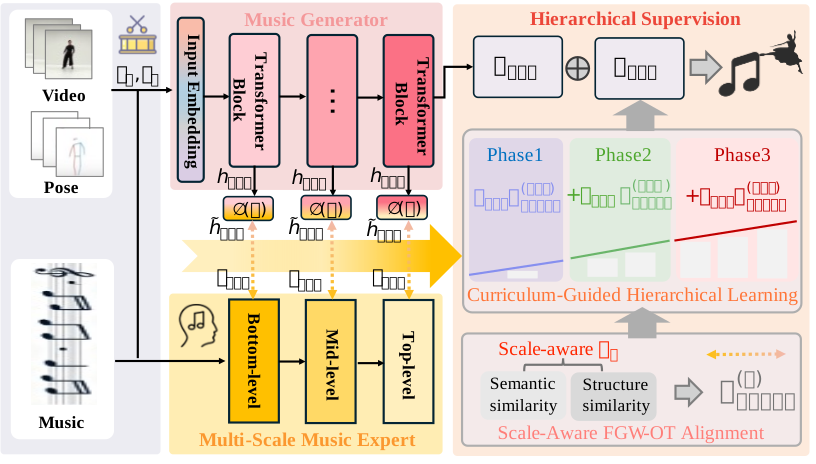
Dance-to-Music (D2M) generation aims to synthesize music that aligns rhythmically and stylistically with dance videos. Existing methods typically rely on sparse dance cues (e.g., rhythm and style) and supervise only the final audio output, which leads to a semantic gap and limits the learning of expressive musical representations. To address these challenges, we propose CMA-OT (Curriculum-guided Multi-scale representation learning with scale-aware Optimal Transport), a framework that leverages a pre-trained music expert to provide hierarchical supervision across multiple semantic levels. CMA-OT includes: Curriculum-guided multi-scale learning, which progressively transfers musical knowledge from coarse to fine levels for effective representation guidance. Scale-aware Fused Gromov-Wasserstein Optimal Transport (FGW-OT), which models soft correspondences between hierarchical expert representations and latent generator features. Extensive experiments on benchmark datasets show that CMA-OT achieves state-of-the-art performance in rhythmic synchronization, perceptual quality, and overall music generation.
Method Pipeline
-
Hierarchical Expert Supervision
Leverages a pre-trained multi-scale music expert to provide coarse-to-fine hierarchical guidance to address the insufficient representation learning caused by semantic gap. Innovation: Bridges the semantic gap beyond sparse dance cues.
-
Curriculum-Guided Multi-Scale Learning
Progressively distill hierarchical knowledge from a pre-trained music expert, aiming to overcome the difficulty of modeling fine-grained temporal semantics under global guidance. Innovation: Gradual learning improves fine-grained temporal modeling.
-
Scale-Aware Alignment with FGW-OT
Aligns dance and music features across scales using Fused Gromov-Wasserstein Optimal Transport, facilitates flexible alignment while preserving both structural consistency and semantic coherence between music and dance. Innovation: Soft, scale-aware alignment outperforms rigid global matching.
Generation Results
Generation Comparison with SOTA Dance-to-Music Methods.